Kafka Dead Letter Queue (DLQ) Implementation Guide
Apache Kafka is a distributed streaming platform that is widely used for building real-time data pipelines and streaming applications. A Dead Letter Queue (DLQ) in Kafka is a concept used to handle messages that cannot be processed due to various reasons such as processing errors, corrupt data, etc. Implementing a DLQ in Kafka helps in isolating problematic messages and ensures that the main processing flow remains efficient.
Understanding Kafka DLQ
The Kafka Dead Letter Queue (DLQ) is a key mechanism in error-handling due to its capacity to handle data corruption or system anomalies. Implementing a DLQ strategy separates problematic messages, ensuring continuous data processing and smooth problem-solving.
Which Kafka errors go to the DLQ and which should retry
Kafka has no broker-level dead letter queue. A plain consumer implements one by producing failed records to a second topic, as the code below does, and Kafka Connect sink connectors add one with errors.tolerance=all and errors.deadletterqueue.topic.name. The decision that matters is which failures retry first and which go straight to the DLQ.
| Failure | What to do | Why |
|---|---|---|
| Deserialization error or corrupt payload | Send to the DLQ immediately | A retry cannot fix a malformed record, and blocking on it stalls every message behind it in the partition |
| Schema or validation failure | Send to the DLQ with the reason in a header | The same record fails the same way on every attempt |
| Downstream timeout or 5xx response | Retry with backoff, then DLQ after a fixed number of attempts | The dependency usually recovers, so a few retries save most records |
| Business rule rejection | Send to the DLQ with the reason | Needs a person or a later process, not a retry |
| Poison pill that crashes the consumer | Send to the DLQ and commit the offset past it | Stops the consumer group from crash-looping on one message |
Copy the source topic, partition, offset, and exception message into record headers so each DLQ record can be traced back and replayed once the cause is fixed.
Step by Step Guide with Code Samples
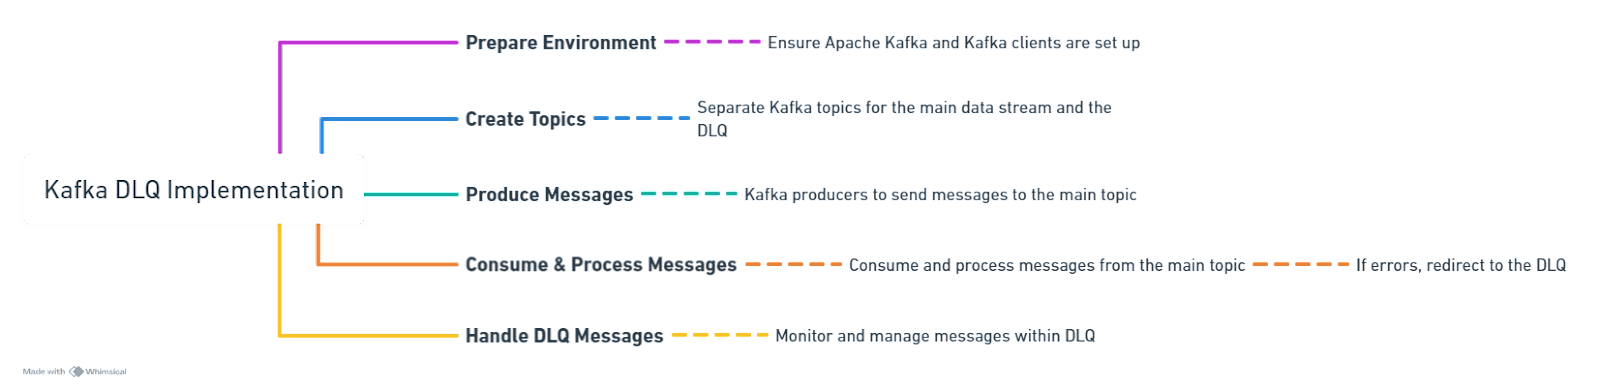
Step 1: Preparing Your Kafka Environment
Ensure Apache Kafka and Kafka clients are set up in your environment. This guide assumes Kafka is already running and accessible.
Step 2: Create Topics for Main Stream and DLQ
Create a Kafka topic for the main stream and another for the DLQ.
# Create main topic
kafka-topics --create --bootstrap-server localhost:9092 --replication-factor 1 --partitions 3 --topic main-topic

# Create DLQ topic
kafka-topics --create --bootstrap-server localhost:9092 --replication-factor 1 --partitions 3 --topic dlq-topic
Step 3: Producing Messages to the Main Topic
Produce messages to the main topic using Kafka producers. This can be done through Kafka client libraries in various programming languages.
from kafka import KafkaProducer
import json

producer = KafkaProducer(bootstrap_servers=['localhost:9092'],
    value_serializer=lambda v: json.dumps(v).encode('utf-8')
)

# Send a message
producer.send('main-topic', {'userId': 123, 'activity': 'login'})
producer.flush()
Step 4: Consuming and Processing Messages
Consume messages from the main topic, process them, and handle errors by producing to the DLQ.
from kafka import KafkaConsumer, KafkaProducer
import json

# Consumer for the main topic
consumer = KafkaConsumer('main-topic',
    bootstrap_servers=['localhost:9092'],
    value_deserializer=lambda m: json.loads(m.decode('utf-8'))
)

# Producer for the DLQ
dlq_producer = KafkaProducer(bootstrap_servers=['localhost:9092'],
    value_serializer=lambda v: json.dumps(v).encode('utf-8')
)

for message in consumer:
    try:
        # Process message
        print(f"Processing message: {message.value}")
        # Example processing logic
        if message.value['userId'] < 0:
            raise ValueError("Invalid user ID")

    except Exception as e:
        print(f"Error processing message: {e}")
        # Produce to DLQ
        dlq_producer.send('dlq-topic', message.value)
        dlq_producer.flush()
Step 5: Handling Messages in the DLQ
Monitor and handle messages in the DLQ. This can involve logging, alerting, or manual intervention to rectify issues.
Best Practices for Kafka DLQ Implementation
- Regularly Review DLQ Messages: Implement logging, alerting, and manual intervention strategies to handle DLQ messages.
- Optimize Topic Configurations: Adjust partition sizes and replication factors based on your specific use case to enhance system performance.
- Handle errors in the consumer first: Catch deserialization and validation failures in the consumer so only records that genuinely cannot be processed reach the DLQ.
Monitoring and Alerting
Monitoring and alerting keep a Kafka-based streaming app healthy. Monitoring Dead Letter Queues (DLQs) helps teams fix issues fast, avoiding wider system impact. This covers strategies and tools for effective DLQ monitoring in Apache Kafka, ensuring quick detection and resolution of problems.
Key Metrics to Monitor
- Queue Size and Growth Rate: Monitoring the size and growth rate of the DLQ provides early warnings of processing issues. A sudden increase in DLQ size could indicate a significant problem in the main processing pipeline.
- Message Age: Tracking how long messages have been sitting in the DLQ can help prioritize issue resolution efforts, especially for time-sensitive data.
- Error Types and Frequencies: Classifying messages by error type and frequency can highlight common issues, guiding targeted troubleshooting and long-term solutions.
Keeping bad records out of your Kafka pipeline
Implementing a Dead Letter Queue in Apache Kafka is essential for handling problematic messages that cannot be processed in the usual manner. It helps in maintaining the integrity and efficiency of the main data pipeline by isolating error-prone messages. The above steps and code samples provide a foundation for integrating DLQs into Kafka-based applications.